Category: Linux Sysadmin

77 posts

I’m used to my Mac where the direction of scrolling was changed to a more ‘natural’ way starting with OSX Lion. It’s the same way scrolling works on mobile devices. When working on Ubuntu, I want to have the same behaviour because I’m used to it.

To do so you need to edit (or create) the .Xmodmap file in your homedir.

This is the default:

cat ~/.Xmodmap
pointer = 1 2 3 4 5

I changed it to:

vim ~/.Xmodmap
pointer = 1 2 3 5 4

This essentially makes the last two (scroll wheel) buttons work the other way around, and that is exactly the behaviour I want.

To enable this setting you have to either logout (and back in) of your X environment, or run this oneliner (Thanks James!):

xmodmap -e "pointer = 1 2 3 5 4"

By editing both the Xmodmap file and running the above oneliner, the new setting works immediately and also keeps working when you (for example) reboot your machine.

Fixing an out-of-sync or corrupt MySQL slave

— 17,857 views — 2 Comments

Sometimes a MySQL slave may get corrupted, or its data may otherwise be unreliable. Usually I clone the data from a slave that is still ok and fix it from there. However, today I run into an issue that made me doubt on the data of any slave. To be absolutely sure the data is consistent on both master and slave, I decided to deploy a new slave with a clone of the master and then redeploy the other slaves from the newly created slave like I normally do with a script.

This blog post describes both methods of restoring replication.

Restoring data directly from the master
We will create a dump from the master server and use it on a slave. To be sure nothing changes during the dump, we issue a ‘read lock’ on the database. Reading will work, writes will wait until we unlock, so please choose the right time to do this maintenance.

To lock all tables run:

FLUSH TABLES WITH READ LOCK;

Now that we have the lock, record the position of the master and write it down. We need it later to instruct the slaves where to continue reading updates from the master.

SHOW MASTER STATUS\G

Example output:

File: bin-log.002402
Position: 20699406

Time to create a sql dump of the current databases. Do this in another session and keep the first one open. This will make sure you’ll keep your lock while dumping the database.

mysqldump -ppassword -u username --add-drop-database databasename table1 table2 > masterdump.sql

After the dump is complete, go back to fist screen and release lock:

UNLOCK TABLES;

This is all we need to do on the master.

Restoring from an already running slave
As an alternative to creating a dump from the master, you can also use a slave’s data. This has the advantage of not having locks on the master database and thus not interrupting service. On the other hand, you will have to be sure this slave’s data is correct.

First stop the slave

SLAVE STOP;

And verify it has stopped

SHOW SLAVE STATUS\G

Output:

Slave_IO_Running: No
Slave_SQL_Running: No
Master_Log_File: bin-log.002402
Read_Master_Log_Pos: 20699406

Record the ‘Relay_Master_Log_File’ and ‘Exec_Master_Log_Pos’. This is the position this slave is at. We will need it later to instruct the new slave.

Create a sql dump of the slave’s data:

/usr/bin/mysqldump --add-drop-database -ppassword -u user -h mysqlserver --databases databasename

Now that we have a dump, we can start the slave again.

SLAVE START;

In the period between the ‘stop’ and ‘start’ slave, everything still works except that updates from the master are not processed. As soon as you start the slave again, the slave catches up with the master.

This method has the advantage that is it easily scriptable. Whenever there’s a problem, you’d run a script with the above commands and have everything fixed in a matter of seconds. That’s a real time saver!

Setting up the new slave
Use scp to securely copy the sql dump we just created above to the slave. Alternatively you may run the ‘mysqldump’ commands directly from the slave as well. Then login and run these commands:

STOP SLAVE;
RESET SLAVE;

Restore the sql dump:

mysql -ppassword -u user databasename < masterdump.sql

You now have a slave with up to date data. We’ll have to instruct the slave where to start updating. Use the result from the ‘master status’ or ‘slave status’ query above depending on the method of your choice.

CHANGE MASTER TO
 master_host='mysqlmaster',
 master_user='replicate_user',
 master_password='replicate_password',
 master_log_file='bin-log.002402',
 master_log_pos=20699406;

Then start the slave:

SLAVE START;

And check the status after a few seconds:

SHOW SLAVE STATUS\G

Output:

Slave_IO_Running: Yes
Slave_SQL_Running: Yes

The slave now runs again with up to date data!

DRBD (Distributed Redundant Block Device) is an open source storage solution that is best compared with a RAID-1 (mirror) between two servers. I’ve implemented this for both our cloud storage as our cloud management servers.

We’re in the process of replacing both cloud storage nodes (that is: everything except the disks and its raid array) and of course no downtime is allowed. Although DRBD is made for redundancy (one node can be offline without impact), completely replacing a node is a bit tricky.

Preventing a ‘split brain’ situation
The most important thing to remember is that only one storage node is allowed to be the active node at all times. If this is violated, a so-called ‘split brain’ happens. DRBD has methods in surviving such a state, but it is best to prevent it from happening.

When discussing this project in our Team, it was suggested to boot the replaced storage node without any networking cables. Usually this is a safe way to prevent the node from interacting with others. In this case, it is not such a good idea: since the new secondary server has the same disks and configuration as the old one unexpeced thing may happen. When booting without networking cables attached, both nodes cannot find one another and the newly booted secondary may decode to become primary itself. A split brain situation will then occur: both nodes will be primary at the same time and access the data. You won’t be able to recover from this, unless you manually decide which node is the master (and lose the changes on the other node). In this case this can be easily decided, but it’s a lot of unneccessary trouble.

Instead, boot the replaced node with network cables connected so the replication network will be up and both nodes immediately will see each other. In our case, this means connecting the 10Gbps connection between the nodes. This connection is used by DRBD for syncing and by Heartbeat for sending the heartbeats. This prevents entering the ‘split brain’ state and immediately starts syncing.

Note: If you want to replace everything including the disks, you’ll have to manually join the cluster with the new secondary node and then sync the data. In this case it doesn’t matter whether the networking cables are connected or not, since this new node won’t be able to become primary anyway.

The procedure
Back to our case: replacing all hardware except for the disks. We managed to successfully replace both nodes using this procedure:

  1. shut down the secondary node
  2. replace the hardware, install the existing disks and 10Gbps card
  3. boot the node with at least the 10Gbps connection active
  4. the node should sync with the primary
  5. when syncing finishes, redundancy is restored
  6. make sure all other networking connections are working. Since the main board was replaced some MAC-addresses changes. Update UDEV accordingly
  7. when all is fine, check if DRBD and Heartbeat are running without errors on both nodes
  8. then stop heartbeat on the primary node. A fail-over to the new secondary node will occur
  9. if all went well, you can now safely shut down the old primary
  10. replace the hardware, install the existing disks and 10Gbps card
  11. boot the node with at least the 10Gbps connection active
  12. the node should sync with the primary
  13. when syncing finishes, redundancy is restored
  14. make sure all other networking connections are working. Since the main board was replaced some MAC-addresses changes. Update UDEV accordingly
  15. the old primary is now secondary
  16. If you want, initialize another fail-over (In our case we didn’t fail-over again, since both nodes are equal powerful)

Congratulations: the cluster is redundant again with the new hardware!

Using the above procedure, we replaced both nodes of our DRBD storage cluster without any downtime.

When migrating an ip-address to another server, you will notice it will take anywhere between 1 and 15 minutes for the ip-address to work on the new server. This is caused by the arp cache of the switch or gateway on the network. But don’t worry: you don’t just have to wait for it to expire.

Why it happens
ARP (Address Resolution Protocol) provides a translation between ip-addresses and mac-addresses. Since the new server has another mac-address and the old one stays in the cache for some time, connections will not yet work. The cache usually only exists for some minutes and prevents asking for the mac-address of a certain ip-address over and over again.

One solution to this problem is to send a command to the gateway to tell it to update its cached mac-address. You need the ‘arping’ utility for this.

Installing arping
There are two packages in Debian that contain arping:

arping - sends IP and/or ARP pings (to the mac address)
iputils-arping - Tool to send ICMP echo requests to an ARP address

I’ve had best results with the ‘iputils’ one, so I recommend to install that one. This is mainly because the other package’s command does not implement the required -U flag.

aptitude install iputils-arping

I haven’t installed arping on CentOS yet, but was told the package is in the RPMForge repository.

Using arping
The command looks like this:

arping -s ip_address -c1 -U ip_addresss_of_gateway

Explanation:
-s is the source ip-address, the one you want to update the mac-address of
-c1 sends just one arping
-U is Unsolicited arp mode to update neighbours’ arp caches
This is followed by the ip-address of the gateway you want to update. In most cases this is your default gateway for this network.

Example: you moved 192.168.0.100 to a new server and your gateway is 192.168.0.254, you’d run:

arping -s 192.168.0.100 -c1 -U 192.168.0.254

After you’ve send the arping, the gateway will update the mac-address it knows of the ip-address and traffic for this ip-address will start flowing to the new server.

Bottom line: whenever you migrate an ip-address to another server, use arping to minimize downtime.

Some handy Git commands I often use

— 107 views — No comments

Push a specific commit (actually: everything up and including this commit):

git push origin dc97ad23ab79a2538d1370733aec984fc0dd83e1:master

Push everything exept the last commit:

git push origin HEAD~:master

The same, now the last two commits:

git push origin HEAD~2:master

Reorder commits, aka rebasing:

git rebase -i origin

Pulling commits from repo to local

git pull --rebase

When a conflict occurs, solve it, then continue:

git rebase --continue

Put local changes apart (shash them)

git stash save stashname

Show all stashes

git stash list

Retrieve a shash

git stash stashname

When you have committed a change and want to revert it:

Make sure all work is committed or stashed!

git checkout 748796f8f2919de87f4b60b7abd7923adda4f835^ file.pp
git commit
git revert HEAD
git rebase -i
git commit --amend

Explanation:
– Checkout the file as it was before your change (line 1)
– commit it (line 2)
– Revert this commit (line 3)
– Using rebase merge (fixup) this commit with the previous commit that contained a change that you want to remove (line 4)
– Finally, rewrite the commit message and you’re done (line 5)

Git rocks!

A few days ago we installed a ‘Battery Backup Unit’ in our secondary storage server. This allows us to turn on the ‘Write Back Cache’. The performance impact was impressive..

Enabling the Write Back Cache means writes are committed to the raid controler’s cache (which is much faster) so you don’t have to wait for the data to be written to disk. Normally, this is a risky operation because when the power goes down unexpectedly the data in the raid controller’s cache is lost. Thanks to the battery the raid controller can finish all of its writes to the disk even there is no more power.

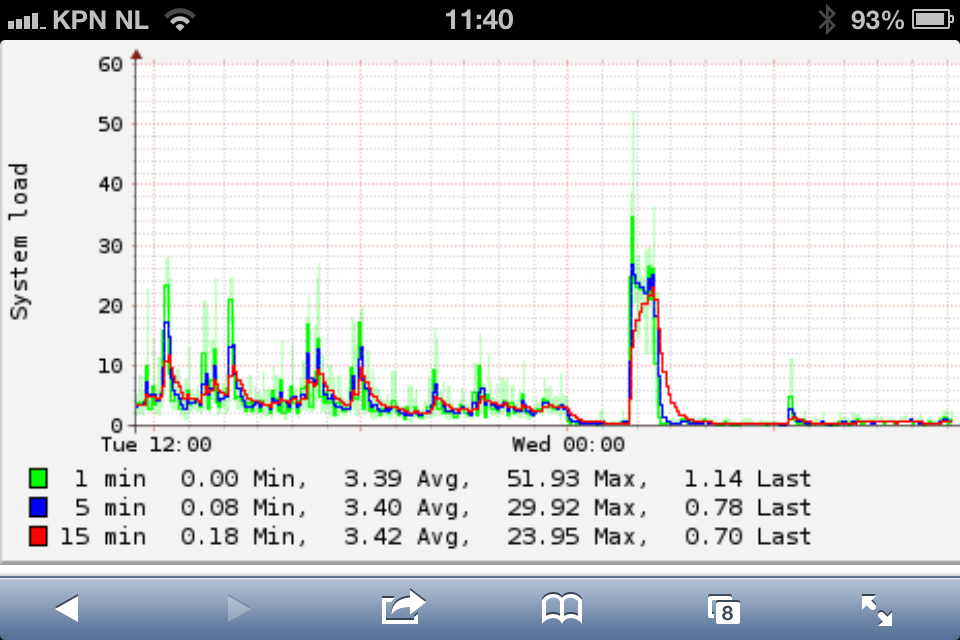
Have a look at the below graph. It shows the load dropped significantly after we’ve installed this battery.

Starting on the left you see normal operations until we switched off the server around midnight. All services kept working by the way, but more about that redundancy magic in another post. The big spike around 1am was caused by syncing the data with the primary storage again after the server came online again. We had not turned on the Write Back Cache at that time. When it finished syncing, we rebooted the server once again, upgraded firmware and activated the Write Back Cache. We immediately saw an performance boost of around 20 times! The small spike around 2am was syncing with the primary storage again, but this time with Write Back Cache enabled. Our load averages now peak at 1 or 2 instead of >20.

Lesson learned: always install a Battery Backup Unit so you can safely turn the Write Back Cache on!

Sometimes it is necessary to block access from a certain ip-address. This can be done easily using route:

route add -host 1.2.3.4/32 reject

While this works, it does not provide the best user experience because from 1.2.3.4 the website now seems down, while it isn’t. A better way is to display an error message instead of the website requested.

I’m using load balancing to distribute the load to different web servers. The software in use is Keepalived. To block a given ip-address, I have the firewall tag it and then make Keepalived forward it to another web server instead. It goes like this:

iptables -t mangle -A PREROUTING -i eth0 \
-p tcp -s 1.2.3.4 --dport http -j MARK --set-mark 2000

This iptables rule just sets a mark ‘2000’ (can be any integer) when a request from 1.2.3.4 comes in for port ‘http’. In keepalived.conf we setup how to handle this fwmark:

virtual_server fwmark 2000 {

delay_loop 6 lb_algo wlc lb_kind NAT persistence_timeout 0 protocol TCP

real_server 10.10.10.1 80 { weight 1 TCP_CHECK { connect_port 80 connect_timeout 3 } } }

As you can see, Keepalived will send the request to ‘10.10.10.1’ which is for example an extra server. There you can display a static page with an error message explaining what’s going on. You can add more capacity by adding another ‘real_server’, if you wish. This will also distribute the load between the real_servers.

Now, when you block an ip-address, instead of the website being ‘down’, you now display an error message. Add your phone number or e-mail address so they can get in touch to fix the problem. In my experience, this approach works better and prevents urgent ‘website down’ calls.

To extend this even further, you can have a script add the fwmark rule above automatically when you detect some sort of abuse you want to block. It’s just as easy as using ‘route’!

Here are three ways to backup your MySQL database(s) and compress the backup on the fly:

1. Dump database ‘dbname’ into a compressed file

mysqldump \
-u user \
-ppassword \
--host=mysql-server \
dbname | \
gzip > dbname_backup.sql.gz

To dump multiple databases, you can either write a ‘for loop’ on a ‘SHOW DATABASES’ query result or use the next command to backup to a single file.

2. Dump all databases into a compressed file

mysqldump \
--all-databases \
-u user \
-ppassword \
--host=mysql-server | \
gzip > dbname_backup.sql.gz

3. Dump database ‘dbname’ except for some tables into a compressed file

mysqldump \
--ignore-table=dbname.ignoredtable1 \
--ignore-table=dbname.ignoredtable2 \
--ignore-table=dbname.ignoredtable3 \
-ppassword \
-u user \
--host=mysql-server \
dbname | \
gzip > dbname_backup.sql.gz

This allows you to skip certain tables that are unimportant (for example cached data) or static (imported from somewhere else). You can skip as many tables as you like. Just repeat the line for each table you want to ignore.

The pipe to gzip in the last line of all examples, makes sure the backup gets compressed before written to disk. You can safely do so to save some disk space. Just remove it to have an uncompressed backup.

When building new computer infrastructure, I find it important to label and document everything properly. This will help you in an emergency, especially if you are not on site and need to instruct someone on the phone. Apart from that, todays infrastructure is quite complex and one cannot remember everything by head. This blog post describes what we used when building our Cloud infrastructure.

First of all, use a separate cable color for each type of connection. We used, for example, different colors for ‘storage’, ‘management’, ‘serial’ and ‘public’ traffic types. This gives a quick overview of the different cables that are in use. Make sure colors are unique, so don’t use black if you’re using black power cables.

The color of the cable is the first distinction, to be even more specific we’ll label every cable as well. Most sys admins know that labeling cables in a data center is not as easy as it seems: the heat and ventilation will eventually make the labels fall off. With this in mind we’re looking for a solution.. Brady BMP21 to the rescue!

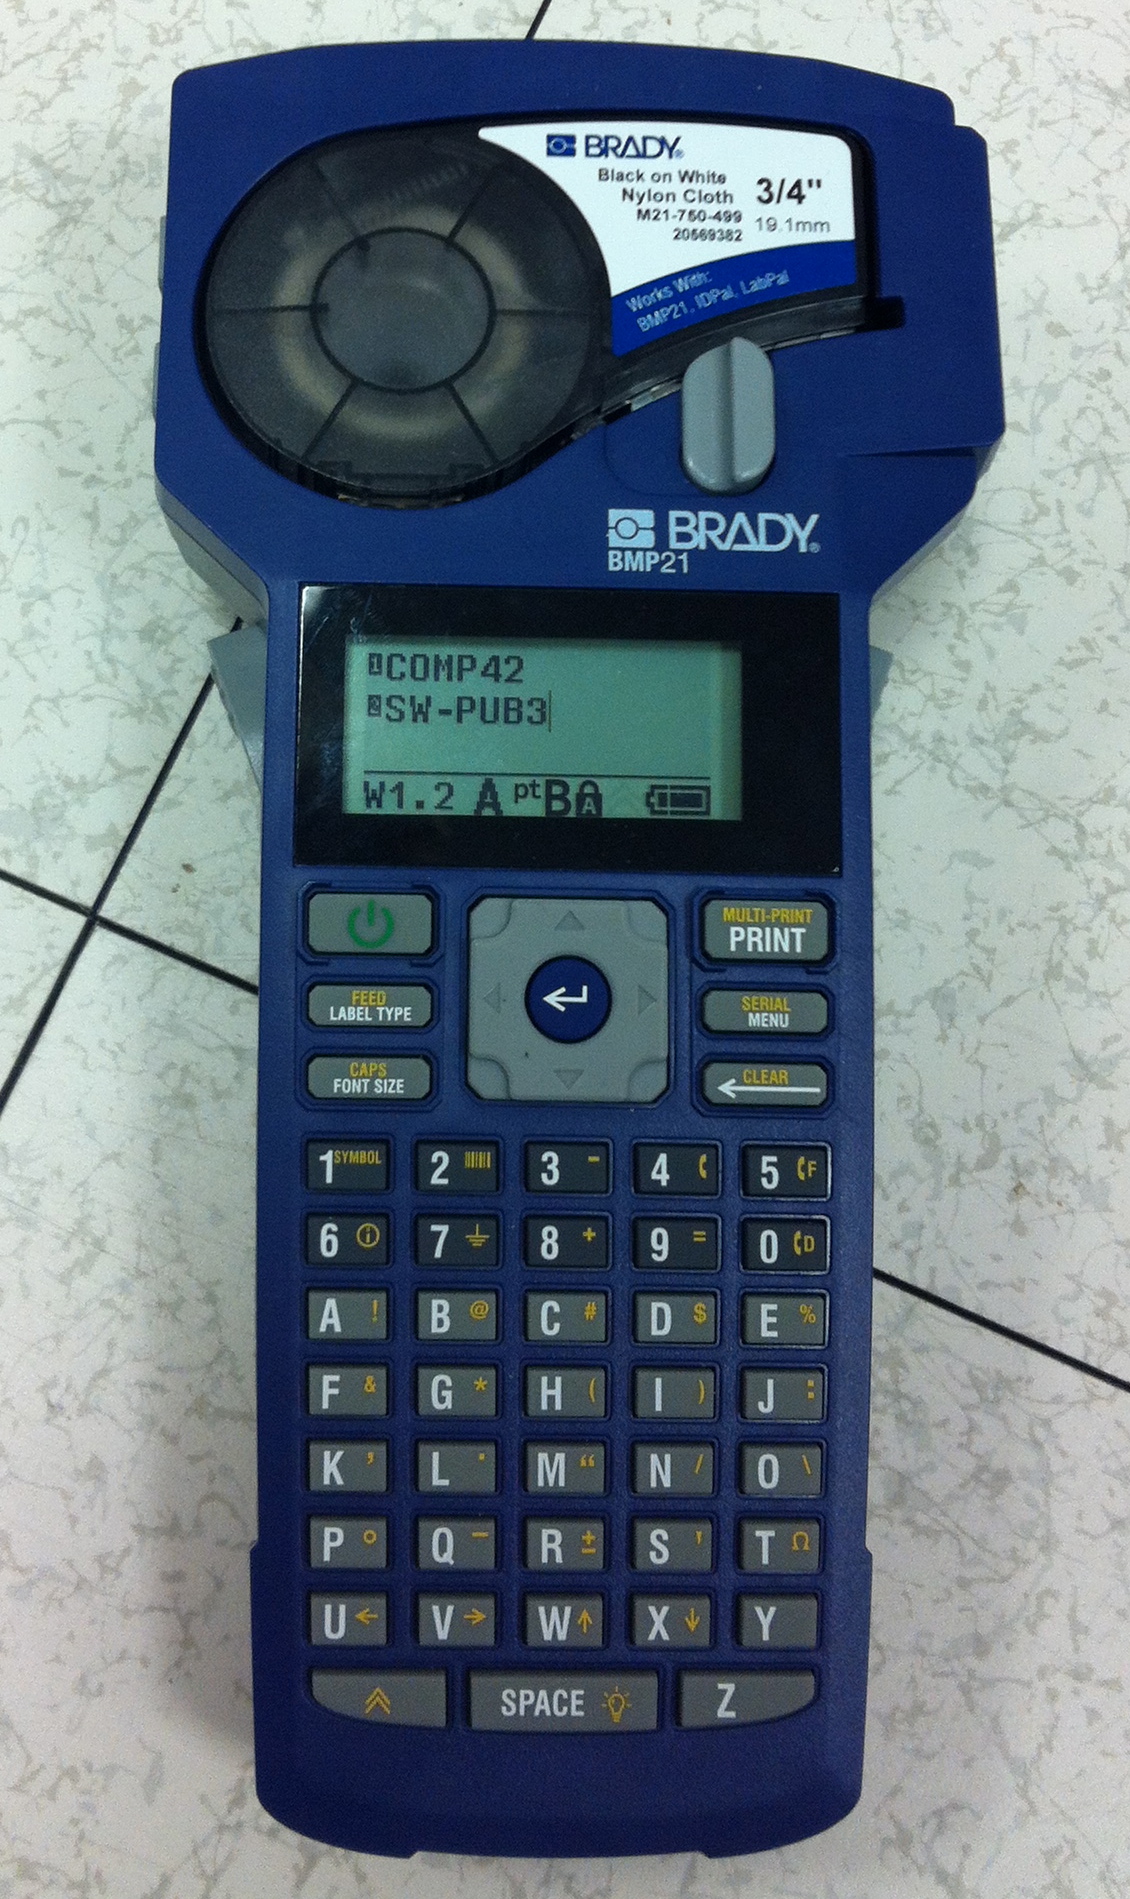
The BMP21 has a keyboard and let’s you enter any description you want. When printing, it produces a label that you can wrap around the cable. This way, the label is very solid connected to the cable and will not fall off.

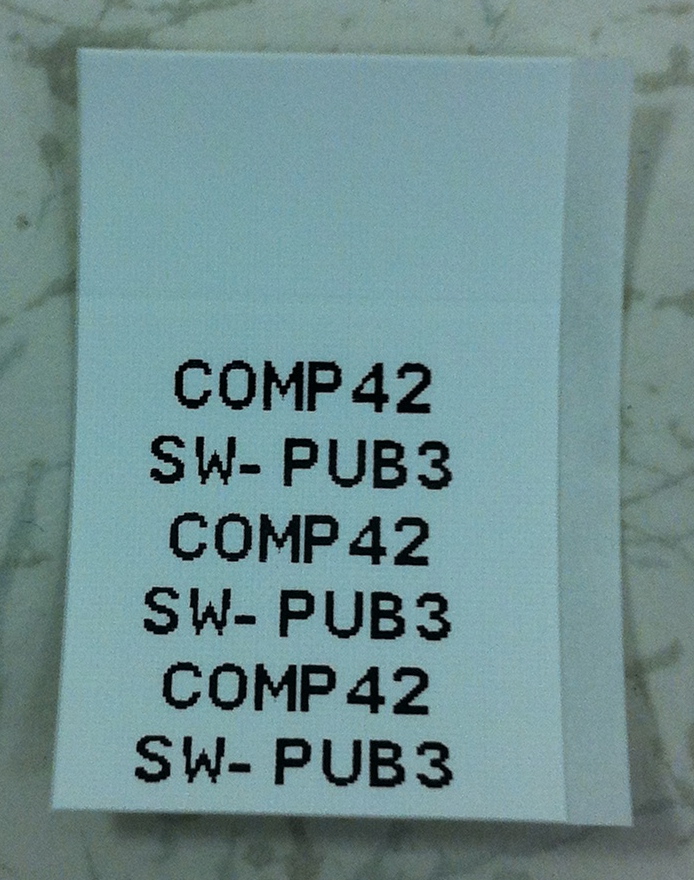
As you can see in the image, it prints the two lines entered on the Brady multiple times. You can wrap the label around the cable and read what’s on it very easy. This also means you won’t have to pull off the cable to be able to read its label. Smart thinking!

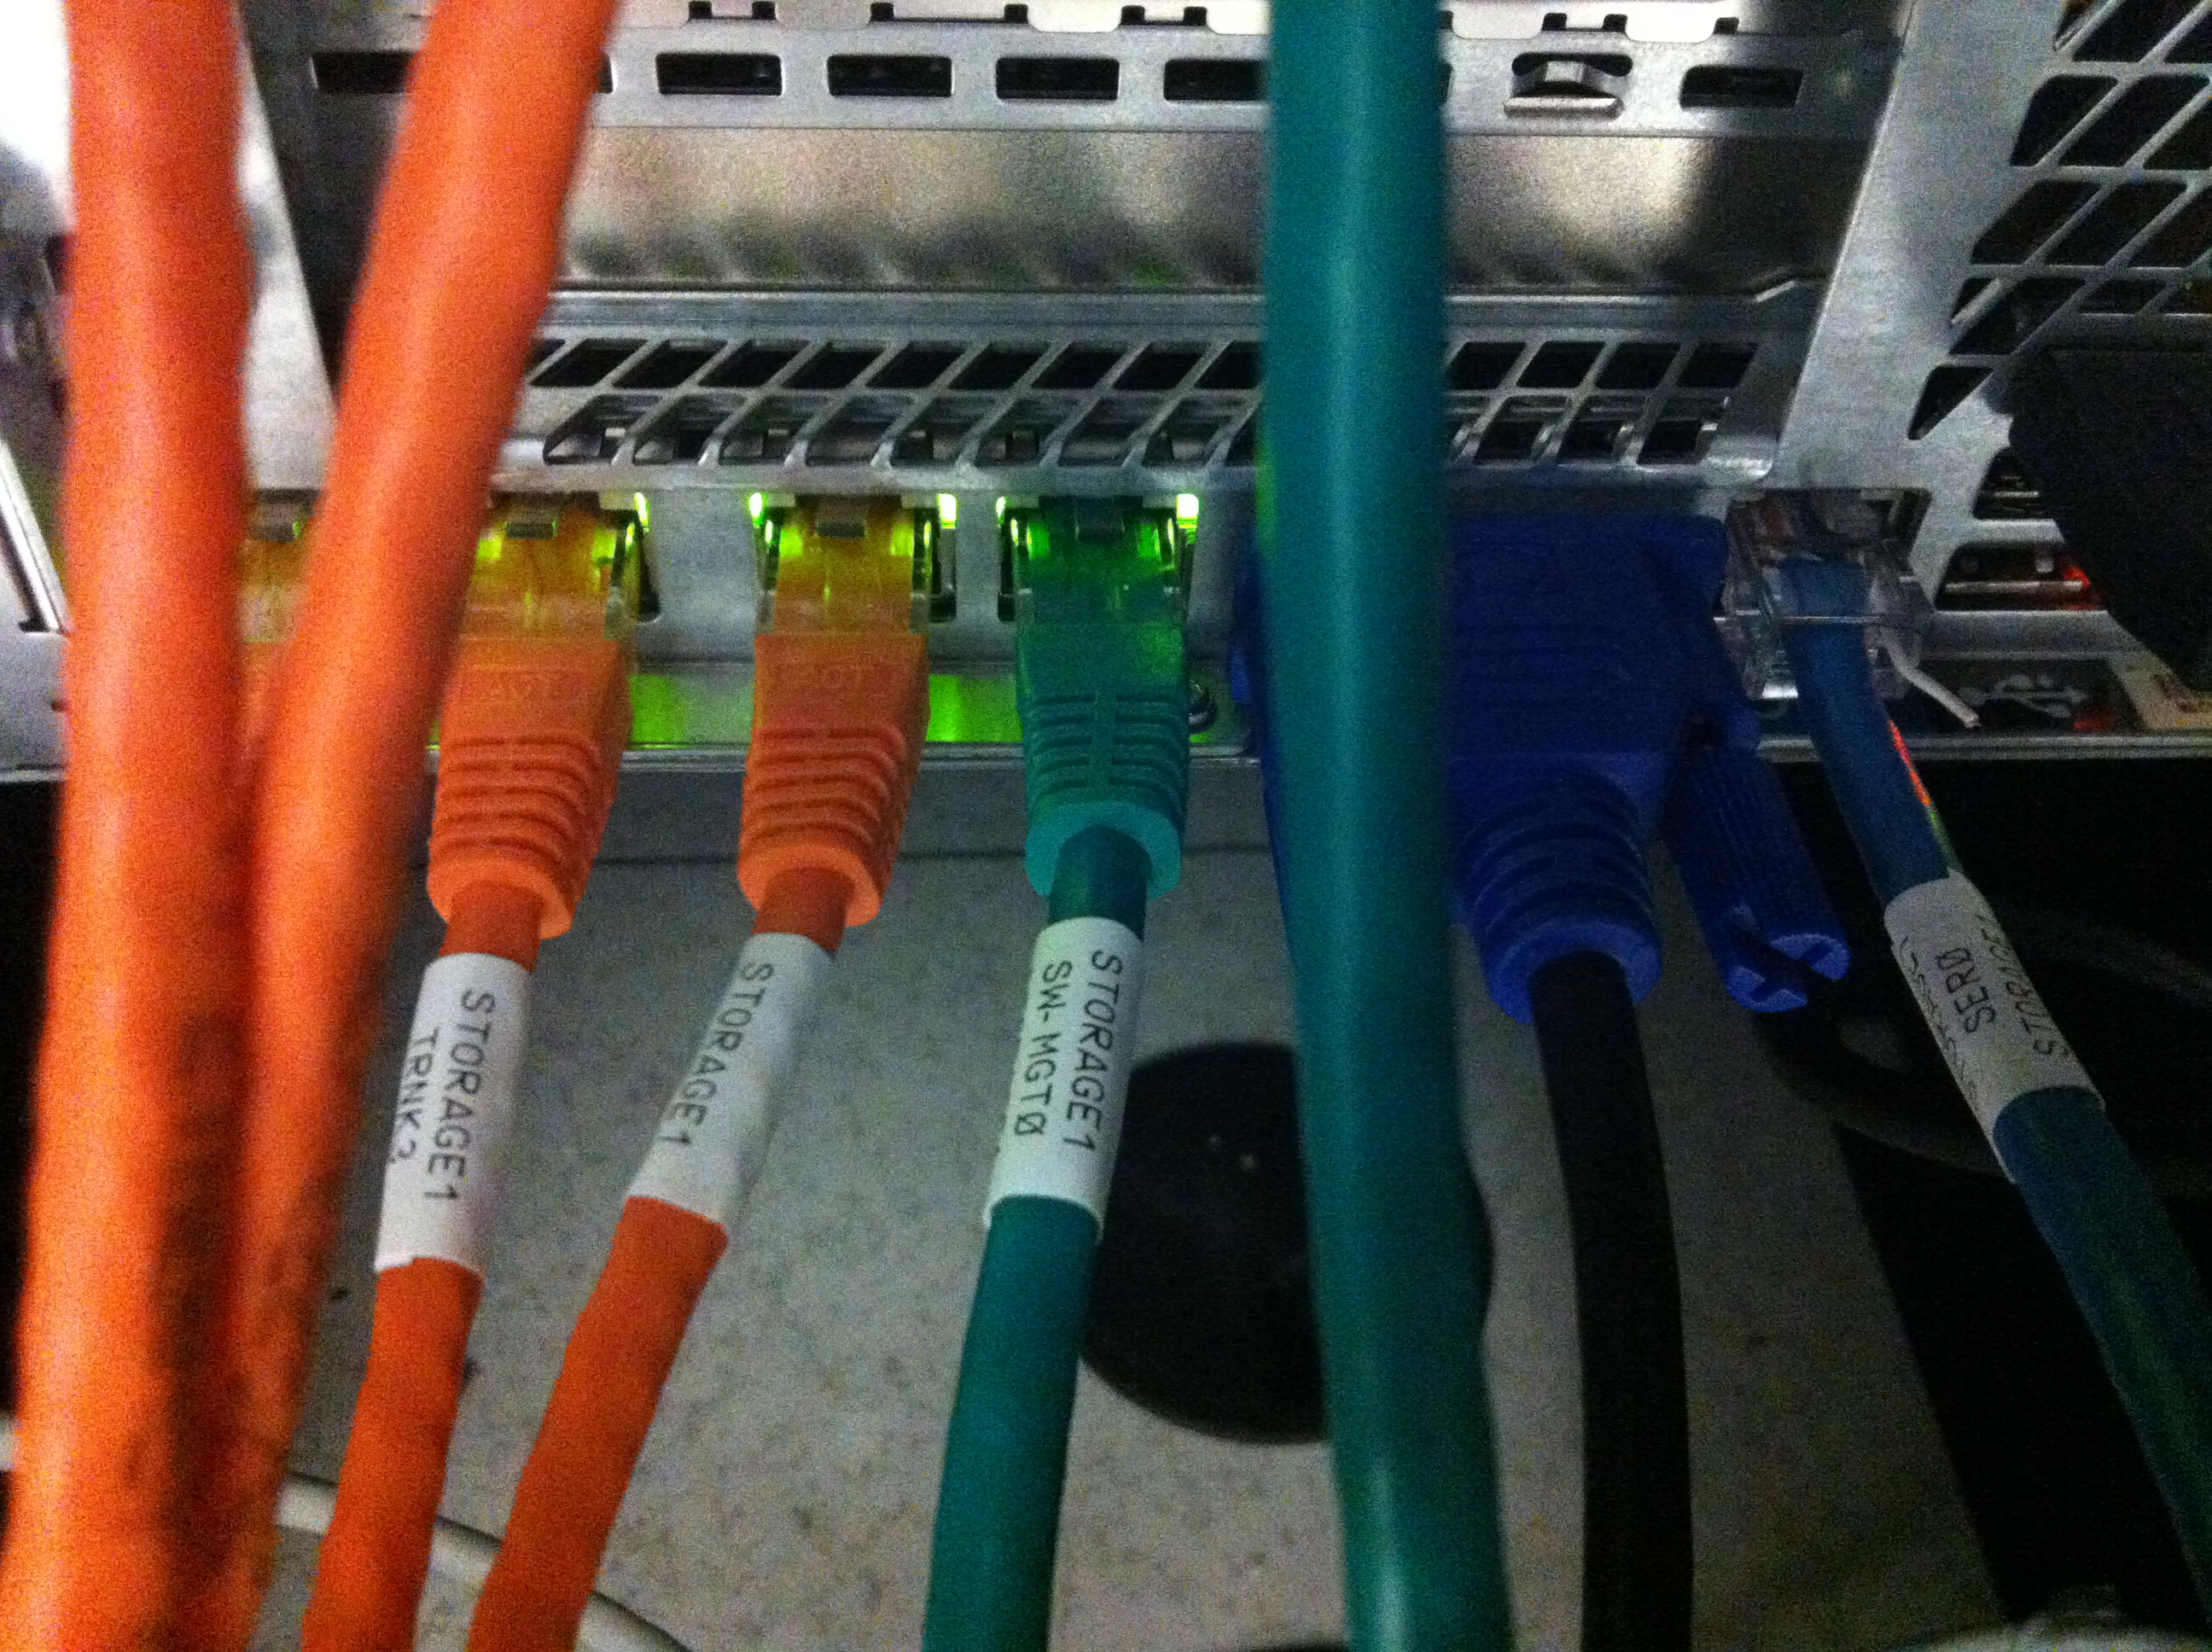
An example of cables we labelled with the BMP21

As you can see it works very well and looks pretty good as well. I’m really satisfied with the device and the labels it produces!

Changes to production systems should be tested on a development system and then be deployed using configuration management (such as Puppet), if you ask me. Sometimes I first run commands by hand (on a test system) to find out the right ones, the right order, etc. In those cases I find it useful to automatically document what I type and be able to ‘replay’ it later on.

Why? Because when I write the Puppet configuration needed to deploy the change, I want to be sure all manual commands I ran make it to the Puppet manifest. Being able to replay what I did allows me to do so with ease.

Here’s how to record your key strokes using the ‘script’ Linux utility:


script change1234.script -t 2> change1234.timing

The ‘script’ utility logs all commands you enter to the file ‘change1234.script’. Furthermore it saves the timing data to a file called ‘change1234.timing’. Beware that everything is saved, including errors and typo’s.

The timing data allows to replay the script using the same timing as when the session was recorded. It gives a good representation of what happened. To replay, simply run:


scriptreplay change1234.timing change1234.script

You can replay it as many times as you like.

The .script and .timing files are just plain text files. This means you can ‘grep’ them to quickly find commands. For example, to display the ‘sed’ commands you used:


grep sed change1234.script

As you can see, saving (and documenting) your commands is easy and offers some nice features. It even allows you to forget what exactly you did… 😉