Here are the slides from my presentation at the CloudStack meetup today in Amsterdam.
Get the code on Github.


Here are the slides from my presentation at the CloudStack meetup today in Amsterdam.
Get the code on Github.


Recently I became a committer in the Apache CloudStack project. Last week when I was working with Rohit Yadav from ShapeBlue he showed me how he had automated the process with a Git alias. I really like it so I’ll share it here as well.
First of all, pull requests are created on Github.com. Rohit created a git alias called simply ‘pr’. This is how it looks like (for the impatient: copy/paste the one-liner below). The command below is for easy reading, it will print a syntax error.
[alias]
pr= "!apply_pr() { set -e;
rm -f githubpr.patch;
wget $1.patch -O githubpr.patch
--no-check-certificate;
git am -s githubpr.patch;
rm -f githubpr.patch;
pr_num=$(echo $1 | sed 's/.*pull\\///');
git log -1 --pretty=%B > prmsg.txt;
echo \"This closes #$pr_num\" >>
prmsg.txt; git commit --amend -m \"$(cat prmsg.txt)\";
rm prmsg.txt; }; apply_pr"
Copy/paste this next two lines into your .gitconfig file (usually located in ‘~/.gitconfig’.):
[alias]
pr= "!apply_pr() { set -e; rm -f githubpr.patch; wget $1.patch -O githubpr.patch --no-check-certificate; git am -s githubpr.patch; rm -f githubpr.patch; pr_num=$(echo $1 | sed 's/.*pull\\///'); git log -1 --pretty=%B > prmsg.txt; echo \"This closes #$pr_num\" >> prmsg.txt; git commit --amend -m \"$(cat prmsg.txt)\"; rm prmsg.txt; }; apply_pr"
This alias allows you to do this:
git pr https://pull-request-urlIt will then fetch the patch, extract the pull request number, adds a note that closes the pull request, finally commits all commits to your current branch. All you have to do is review and push.
Let’s demo this on a pull request I openend on the CloudStack documentation. Goes like this:
git pr https://github.com/apache/cloudstack-docs-rn/pull/21--2015-05-24 19:22:54--
https://github.com/apache/cloudstack-docs-rn/pull/21.patch
Resolving github.com... 192.30.252.130
Connecting to github.com|192.30.252.130|:443... connected.
HTTP request sent, awaiting response... 302 Found
Location: https://patch-diff.githubusercontent.com/raw/apache/cloudstack-docs-rn/pull/21.patch [following]
--2015-05-24 19:22:54--
https://patch-diff.githubusercontent.com/raw/apache/cloudstack-docs-rn/pull/21.patch
Resolving patch-diff.githubusercontent.com... 192.30.252.130
Connecting to patch-diff.githubusercontent.com|192.30.252.130|:443... connected.
HTTP request sent, awaiting response... 200 OK
Cookie coming from patch-diff.githubusercontent.com attempted to set domain to github.com
Length: unspecified [text/plain]
Saving to: 'githubpr.patch'
githubpr.patch [ <=> ] 9.23K --.-KB/s in 0.002s
2015-05-24 19:22:55 (4.96 MB/s) - 'githubpr.patch' saved [9449]
Applying: add note on XenServer: we depend on pool HA these days
Applying: remove cached python classes and add ignore file for it
Applying: explicitly mention the undocumented timeout setting
[master 08e325d] explicitly mention the undocumented timeout setting
Author: Remi Bergsma <[email protected]>
Date: Sun May 24 08:28:43 2015 +0200
3 files changed, 21 insertions(+), 3 deletions(-)
The pull request has 3 commits that are now committed to the current branch. Check the log:
git log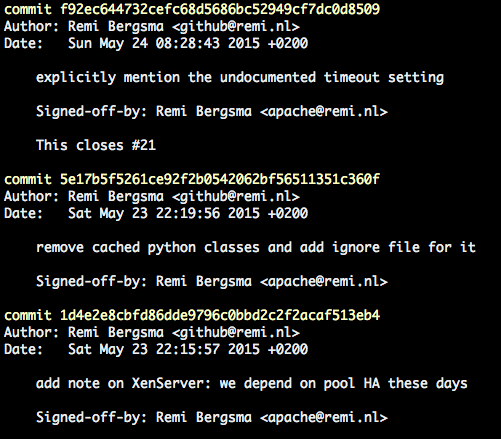
Isn’t that great? Now all you have to do is push it to a upstream repository.
Signed-off-by
This is achieved by adding the following to ‘.gitconfig’:
[format]
 signoff = true
Thanks Rohit for sharing!
 XenServer and Apache CloudStack work nicely together and form an easy-to-go couple for many companies. However, not many people know that recent releases changed the cooperation between the two drastically.
I’m not only talking about the shiny new Apache CloudStack 4.5 release, but the change was back ported to recent releases of 4.3.x and 4.4.x as well. This means that if you run XenServer and CloudStack, you need the review the information below carefully.
 I can understand why almost nobody knows, because this was not well discussed and did not end up in the release notes nor documentation either. I talked to many people about this at meetups and thought it’d be useful to write some of it in a blog. I tested it on both versions 6.2 and 6.5.
What did change?
XenServer works with the concept of a pool-master that coordinates a lot of stuff in the cluster. CloudStack sends its instructions to the pool-master. What did change? CloudStack used to elect a new XenServer pool-master in the event of a failing pool-master. In the new behaviour CloudStack does nothing and relies on the XenServer poolHA feature to be enabled. XenServer itself now elects a new pool-master.
Why is this a problem?
First of all, if you don’t know and upgrade CloudStack, you will not recover automatically anymore from a pool-master failure. This will most likely cause you to have some stress while you work to getting a failed pool-master back up and running. It doesn’t recover automatically anymore, because CloudStack now relies on XenServer to handle this event, but by default this feature is not enabled. No pool-master means no changes are being made (no VMs start, etc).
Why was this changed?
If you ask me, this is a tricky one. The reason for doing it, was sent to the cloudstack-dev list. The mail points to issues CLOUDSTACK-6177 and CLOUDSTACK-5923 but there’s only a vague description there:
“When XS master is down, CS uses pool-emergency-transition-to-master and pool-recover-slaves API to choose a new master, this API is not safe, and should be only used in emergent situation, this API may cause XS use a little bit old (5 minutes old) version of XS DB, some of object may be missing in the old XS DB, which may cause weird behaviour, you may not be able to start VM.”
In other words, there is a small corner-case in which something not specified can go wrong that might prevent starting VMs. Well, if you upgrade CloudStack and do not turn ON the poolHA feature, guess what? You have a 100% change that no VM will start on the whole cluster. Doesn’t make sense to me. At all.
Another thing that bugs me is that there were no replies on the dev-list and that it was silently merged without proper discussion and documentation. I sent an e-mail about it to the cloudstack-dev list, but not too many people seem to care. On the other hand, I do get some questions about it from time to time.
How did we find out?
We had an outage and needed to recover manually, after which we started looking for the Root Cause of this. If you look at the code and the commit messages, you find this changed behaviour that relies on ‘XS HA’ aka XenServer poolHA. This is the commit; it clearly removes the PoolEmergencyTransitionToMaster function that used to elect a new pool-master.
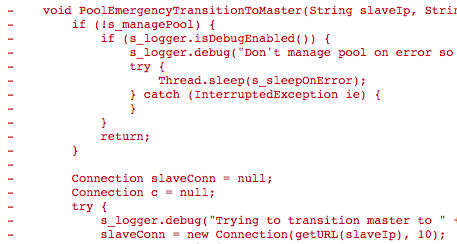
A tricky change
Turning on XenServer poolHA seems easy, but there are pitfalls that can have drastic consequences. Let’s start with the basics. To turn it on, use the ‘xe pool-ha-enable‘ command. You need a Storage Repository that is shared to write heartbeats to. In our case, we already used NFS, so we reused that. If you have no shared SR, be sure to create one.
The XenServer documentation (PDF) says:
“Verify that you have a compatible Storage Repository (SR) attached to your pool. iSCSI, NFS or Fibre Channel are compatible SR types” … “Enable HA on the pool: xe pool-ha-enable heartbeat-sr-uuids=“
So I came up with this:
NFSUUID=$(xe sr-list type=nfs params=uuid --minimal)
xe pool-ha-enable heartbeat-sr-uuids=$NFSUUID
The biggest pitfall is that you need to specify the timeout, or else it will use a 30 second default. You’re right, the Citrix manual (linked above) does not tell you this. This caused another outage, this time we lost a whole cluster. Trust me, it was no fun. Fortunately we had application redundancy over multiple clusters. Anyway, my advise: always specify the timeout.
A 30 second timeout means that when your storage or network is unavailable for 30 seconds, all hosts in the cluster will be fenced and reboot. No VM will keep running on that cluster. We use 180 seconds because that is more or less what the ring buffers can hold in our case. Enable HA like this:
NFSUUID=$(xe sr-list type=nfs params=uuid --minimal)
xe pool-ha-enable heartbeat-sr-uuids=$NFSUUID ha-config:timeout=180
If you did enable it already, first disable it:
xe pool-ha-disableTo check if HA is enabled, run:
xe pool-list params=all | grep -E "ha-enabled|ha-config"Output looks like this:
 ha-enabled ( RO): true
 ha-configuration ( RO): timeout: 180
To see all HA properties:
xe pool-list params=all | grep ha- ha-enabled ( RO): true
ha-configuration ( RO): timeout: 180
ha-statefiles ( RO): e57b08d0-aada-4159-c83d-3adea565d22e
ha-host-failures-to-tolerate ( RW): 1
ha-plan-exists-for ( RO): 1
ha-allow-overcommit ( RW): true
ha-overcommitted ( RO): falseThe first three show HA being on, a timeout of 180 seconds and the heartbeats will be written to the storage repository (SR) with uuid e57b08d0-aada-4159-c83d-3adea565d22e.
The setting ‘ha-host-failures-to-tolerate‘ is automatically calculated by XenServer. In our case, it is not important as we do not protect any VMs, we just use the poolHA feature. You can leave this default.
I asked XenServer community manager Tim Mackey about overcommitting when I met him at the CloudStack Day in Austin, TX. He said:
“Setting ha-allow-overcommit to true indicates that XenServer should calculate its HA plan using optimistic placement. Since the point of enabling HA for CloudStack is to handle host failures, but that CloudStack handles all VM level HA, no VMs will actually be protected by XenServer HA. The net result is the value for ha-allow-overcommit shouldn’t matter for CloudStack.”
You need at least three nodes!
Your XenServer pool needs to be at least three XenServers or else the HA feature will not work as expected. Why? Because the poolHA tries to detect isolation. If it cannot see any other host, it assumes it is isolated and self-fences. So, if you have two XenServers and one crashes, the other one becomes isolated and will self-fence. Both are now down, and the bad news is: they will keep fencing because they never are up at the same time. So, they keep thinking they have become isolated from the pool. Nice for a lab, but don’t do this in production.
About Self-Fencing
To prevent corruption, XenServer poolHA fill fence itself if it cannot reach the Storage Repository any more where it is supposed to write its heartbeat. You may find messages like this in the logs:

Warning: Do not protect the VMs
XenServer should only take care of the pool-master failover and the fencing not about restarting VMs as this is CloudStack’s job. The documentation of XenServer instructs you to do it, but just don’t if you use CloudStack. Otherwise both CloudStack and XenServer will try to recover VMs and it will become messy eventually leading to corrupted VMs.
To check HA on VMs is off, run this command:
xe vm-param-get uuid=<UUID> param-name=ha-restart-priorityIt should return an empty result. If it does not, make sure to use ‘xe vm-param-set‘ to set it empty.
Warning: Licensing considerations
Before XenServer 6.2, HA was a paid feature. Users of 6.0.2 or 6.1 need a license for this to work. The bad news: if you use a modern CloudStack version, you will need to manually elect a new pool-master.
Warning: PoolHA blocks certain operations
Many operations related to XenServer and CloudStack have changed because they are not allowed when poolHA is enabled.
For example, adding a new XenServer to CloudStack has to be done in a different way as well. If you just add it, you’ll get a message like this in the UI:
The API does the same:
Error 530: Unable to add the hostLooking at the logs of the management server shows why:
2015-05-23 08:59:03,064 WARN [c.c.h.x.d.XcpServerDiscoverer] (180595423@qtp-818975168-33:ctx-7c741014 ctx-79b8e039) Please join the host 192.168.22.13 to XS pool f4d78d74-1985-d8d7-f1c4-f7b2b5c213b6 through XC/XS before adding it through CS UIAh, you need to add it to the XenServer pool first. In other words, when building a new cluster: first you need to make a complete XenServer pool, then add one of them to CloudStack that will discover the others and add them in one go.
When you add an extra XenServer to an existing cluster, be sure to add it to XenServer first and then to CloudStack. Start with disabling poolHA, do your thing and enable poolHA again. if you add more than one new XenServer, adding one to CloudStack will discover them all.
Another example. You can no longer remove the pool-master from CloudStack. You first need to go to the XenServer and designate a new pool-master. That also sounds simple, but it is not allowed when poolHA is enabled. So, you have to:
Poehee. Same goes for patching, as you change the pool-master as well.
In short: Enabling poolHA brings challenges when automating these operations, as we now need to talk both to CloudStack and XenServer.
Known issue: CloudStack reports Alert state
When one of the XenServer nodes crashes for some reason, be it hardware or else, it sometimes is put into “maintenance mode”. Not in CloudStack, but in the pool itself. CloudStack will report an Alert state and refuse to work with it. You need to manually enable the host again using the ‘xe host-enable‘ command. CloudStack will then automatically enable it again and start using it.
How to go from here?
To be honest I don’t like the “two captain” approach. In my opinion CloudStack is the orchestrator and needs to be in control. Any hypervisor should be dumb and do what the orchestrator (in this case CloudStack) tells it to do. Period. Like how KVM works, I love the simplicity.
I’m investigating if we can get the best of both worlds by detecting whether HA is turned ON (one-liner shown above) and implement a behaviour based on that. If HA is turned OM, do what 4.4+ does today. If it’s turned OFF, do the old behaviour. This essentially makes it possible to choose between the options and I’m quite sure I’ll disable HA again. It is also backwards compatible for those relying on this feature now.
Another thing to improve is the documentation. As a start, I‘ve sent a first pull-request to update it.
Conclusion
If you run XenServer and CloudStack, you may want to enable poolHA on XenServer or else you will have to manually elect a new pool-master in the event of a crash. Be sure to configure it properly and remember that poolHA when enabled brings in extra steps to certain operations. I hope this blogs helps people achieving nice uptimes and easy maintenance.
Update (June 1st):
Things started rolling and Citrix updated their XenServer documentation to include the HA timeout settings. Nice!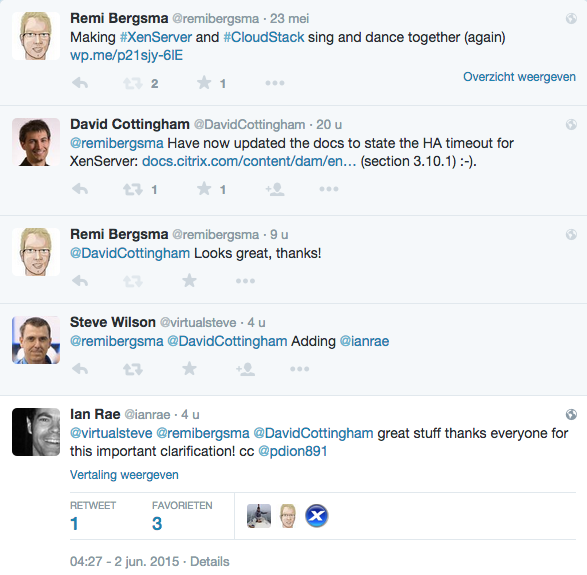
At work we’re creating a CloudStack development environment that can be created and destroyed as we go. One of the requirements is to quickly create a couple of hypervisors to run some tests. KVM is easy: they are just Linux boxes with some extra packages. XenServer is a different story.
Imagine you create a XenServer by installing it from ISO, then saving it as a template. Then create two instances from it called xen1 and xen2. If you try to add them to CloudStack, you’ll notice only the first one succeeds.
The logs tell you why it did not work:
Skipping xen2 because 7af82904-8924-49fa-b0bc-49f8dbff8d44 is already in the database.Hmm.. so would both have the same UUID? Let’s see. To get the UUID of a XenServer, simply run this:
xe host-listThe output of both my XenServers is below:
[root@xen1 ~]# xe host-list
uuid ( RO) : 7af82904-8924-49fa-b0bc-49f8dbff8d44
 name-label ( RW): xen1
 name-description ( RW): Default install of XenServer
[root@xen2 ~]# xe host-list
uuid ( RO) : 7af82904-8924-49fa-b0bc-49f8dbff8d44
name-label ( RW): xen2
name-description ( RW): Default install of XenServerCloudStack is now confused and wants them to have a unique UUID, which makes sense.
It was quite a puzzle to come up with an automatic process. A couple of colleagues of mine all contributed a part and we finally came up with something that works on both XenServer 6.2 and 6.5.
First, you need to generate new UUIDs in ‘/etc/xensource-inventory’ for both the XenServer and the dom0. Do this after you’ve stopped the Xapi process. You should also wipe the state.db of Xapi.
An important part consists of running ‘/opt/xensource/libexec/create_templates‘ and then reset the network, after which the XenServer reboots.
To make it easy for others, we’ve published the script on Github.
It should be run as a ‘first boot’ script. It needs two reboots to fully complete the procedure, and it does this automatically.
When you look at the UUIDs again after running the script:
[root@xen1 ~]# xe host-list
uuid ( RO) : ae2eeb9b-ed7e-4c3c-a619-376f8a632815
 name-label ( RW): xen1
 name-description ( RW): Default install of XenServer
[root@xen2 ~]# xe host-list
uuid ( RO) : 50adc2d0-8420-425c-a1c8-68621bd68931
name-label ( RW): xen2
name-description ( RW): Default install of XenServerThey’re unique now! Adding them works fine… but hey, they have the same name in CloudStack? This is due to the name-label that also needs to be set to the new hostname.
xe host-param-set uuid=\$(xe host-list params=uuid|awk {'print \$5'} | head -n 1) \
name-label=\$HOSTNAME
Just use our script and you’ll be fine!
Update:
Rohit from ShapeBlue, a fellow engineer working on CloudStack, almost immediately responded to my blog:
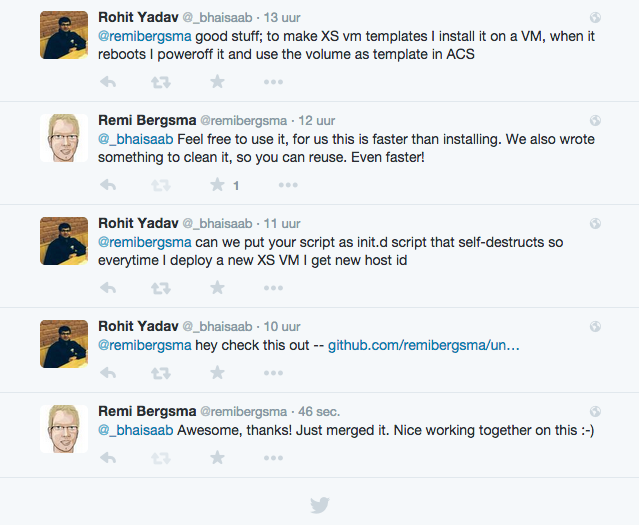
He sent me a pull request that turns the script into an init-script for use in XenServer. That makes it even easier for others to use it. He also updated the documentation:
To use this in a VM template for testing XenServer hosts in VMs:
scp xenserver_make_unique.sh root@xenserver-host-ip:/opt/
scp init.d/xenserver_make_unique root@xenserver-host-ip:/etc/init.d/
ssh root@xenserver-host-ip “chmod +x /etc/init.d/xenserver_make_unique && chkconfig xenserver_make_unique on”
When the XenServer host starts for the first time, it would reset the host uuid by running the script from /opt/xenserver_make_unique.sh, then remove the init.d script and reboot the host.
You only need to do this once in your template, and all XenServers you will create from it will be unique. Enjoy!
Watch my talk “Operating CloudStack – Sharing my Tool Box” that I presented at CloudStack Day Austin, on April 16th 2015.
The talk was originally written for ApacheCon North America and I presented it there a few days earlier. It was great to be able to do the talk again and reach an even bigger audience!
The slides can be found in this post, and the code can be found on Github.
At CloudStack Day I had a ~25 minute slot, instead of a 45 minute slot at ApacheCon, so it had to be a bit fast 😉
Here are the slides from my presentation at both ApacheCon and CloudStack Day in Austin, TX.
 As KVM seems more and more interesting, at work we wanted to do a Proof-of-Concept. The KVM hypervisor cluster had to be controlled by CloudStack and also integrate with NSX (formerly known as Nicira).
NSX is owned by VMware these days and is one of the first Software Defined Networking solutions. At Schuberg Philis we use this since early 2012.
Choosing an OS
To me, the most interesting part of KVM is the fact you only need a very basic Linux box with some tooling and you have a nice modern hypervisor ready to rock. Since we’re using CloudStack to orchestrate everything, we do not need cluster features. In fact, this prevents the “two captain” problem that we sometimes encounter with XenServer and VMware ESX. We compared Ubuntu with CentOS/RHEL and both work fine. It all depends on your needs.
Installing KVM
Installing the software is pretty straight forward:
CentOS:
yum install kvm libvirt python-virtinst qemu-kvm bridge-utils pciutilsUbuntu:
apt-get install qemu-kvm libvirt-bin bridge-utils virt-manager openntpdInstalling Open vSwitch
Open vSwitch is a multilayer virtual switch and it brings a lot of flexibility in the way you can create interfaces and bridges in Linux. There are two options here. If you need STT tunnels, you need the NSX patched version of Open vSwitch. If you need VXLAN or GRE tunnels, you can use the open source version that comes with Ubuntu and CentOS. Both ship version 2.3.1 which works perfectly fine.
CentOS:
yum install openvswitch kmod-openvswitchUbuntu:
apt-get install openvswitch-switchConfiguring Open vSwitch
Instead of classic Linux bridges, we use Open vSwitch bridges. In our POC lab environment, we were using HP DL380 G9 servers that have 2 10Gbit NICs to two Arista switches. They run a LACP bond and on top of this we create the bridges for KVM to use. Because we setup the Open vSwitch networking over and over again while debugging and testing different OS’es, I wrote a script that can quickly configure networking. You can find it at Github.
To give some quick pointers:
Create a bridge:
ovs-vsctl add-br cloudbr0Create an LACP bond:
ovs-vsctl add-bond cloudbr0 bond0 eno49 eno50\
bond_mode=balance-tcp lacp=active other_config:lacp-time=fast
Create a so-called fake bridge (with a VLAN tag):
ovs-vsctl add-br mgmt0 cloudbr0 123Get an overview of current configuration:
ovs-vsctl showGet an overview of current bond status:
ovs-appctl show/bondExample output:
---- bond0 ----
bond_mode: balance-tcp
bond may use recirculation: yes, Recirc-ID : 300
bond-hash-basis: 0
updelay: 0 ms
downdelay: 0 ms
next rebalance: 9887 ms
lacp_status: negotiated
active slave mac: fc:00:00:f2:00(eno50)
slave eno49: enabled
may_enable: true
hash 139: 3 kB load
slave eno50: enabled
active slave
may_enable: true
hash 101: 1 kB load
hash 143: 5 kB load
hash 214: 5 kB load
hash 240: 5 kB load
Add hypervisor to NSX
For now I assume you already have a NSX cluster running capable of acting as a controller/manager for Open vSwitch. If you don’t know NSX, have a look because it’s awesome.
We do need to connect our Open vSwitch to the NSX cluster. To do that, you need a SSL certificate. This is how you generate one:
cd /etc/openvswitch
 ovs-pki req ovsclient
 ovs-pki self-sign ovsclient
 ovs-vsctl -- --bootstrap set-ssl \
 "/etc/openvswitch/ovsclient-privkey.pem" \
 "/etc/openvswitch/ovsclient-cert.pem" \
 /etc/openvswitch/vswitchd.cacert
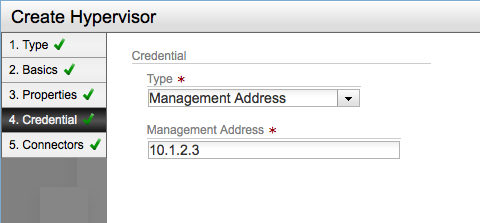
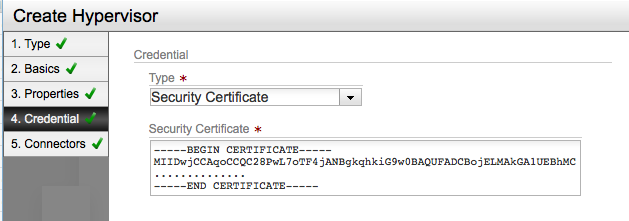
Next, add the hypervisor to NSX. You can either set the authentication to be ip-address based (it will then exchange certificates on connect) or copy/paste the certificate (ovsclient-cert.pem) to NSX at once. The first method allows for easier automation. I’m showing the UI here, but of course you can also use the API to add the hypervisor.
The final step is to connect Open vSwitch to NSX:
ovs-vsctl set-manager ssl:10.10.10.10:6632Then NSX should show green lights and tunnels are being created.
To get an idea of what’s going on, you can run:
ovs-vsctl list manager
ovs-vsctl list controller
ovs-vsctl show
Debugging this can be done from the command line (check Open vSwitch logs) or from NSX.
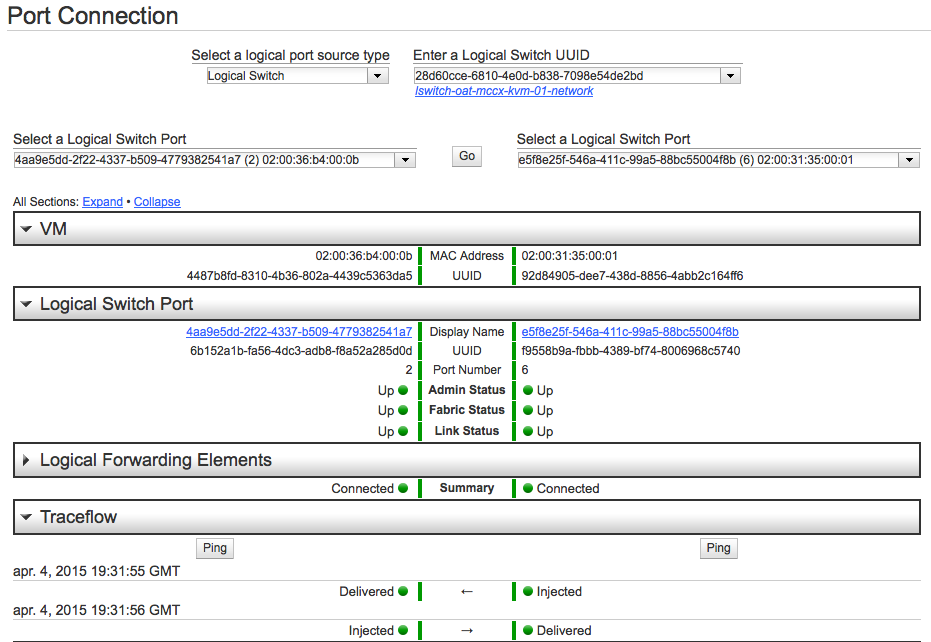
At this point, NSX is controlling our Open vSwitch.
Setting up the CloudStack agent
When running KVM, CloudStack runs an agent on the hypervisor in order to configure VMs.
Installing the agent is simply installing a RPM or DEB package. Depending on the version you will use different repositories. At Schuberg Philis, we build our own packages that we serve in a repository.
Because we’re using Open vSwitch, some settings need to be tweaked in the agent.properties file, found in /etc/cloudstack/agent.
echo "libvirt.vif.driver=com.cloud.hypervisor.kvm.resource.OvsVifDriver" \
>> /etc/cloudstack/agent/agent.properties
echo "network.bridge.type=openvswitch" \
>> /etc/cloudstack/agent/agent.properties
You may also want to set the log level to debug:
sed -i 's/INFO/DEBUG/g' /etc/cloudstack/agent/log4j-cloud.xmlCloudStack requires some KVM related settings to be tweaked:
# Libvirtd
echo 'listen_tls = 0' >> /etc/libvirt/libvirtd.conf
echo 'listen_tcp = 1' >> /etc/libvirt/libvirtd.conf
echo 'tcp_port = "16509"' >> /etc/libvirt/libvirtd.conf
echo 'mdns_adv = 0' >> /etc/libvirt/libvirtd.conf
echo 'auth_tcp = "none"' >> /etc/libvirt/libvirtd.conf
libvirt-bin.conf
sed -i -e ’s/libvirtd_opts="-d"/libvirtd_opts="-d -l"/’

/etc/init/libvirt-bin.conf
service libvirt-bin restart
qemu.conf
sed -i -e ’s/#vnc_listen.*$/vnc_listen = “0.0.0.0”/g’

/etc/libvirt/qemu.conf
On CentOS 7 Systemd ‘co-mounts’ cpu,cpuacct cgroups, and this causes issues for launching a VM with libvirt. On the mailing list this is the suggested fix
Edit /etc/systemd/system.conf and pass empty string to JoinControllers parameter. Then rebuild the initramfs via ‘new-kernel-pkg –mkinitrd –install `uname -r`’.
Something I currently don’t like: SELinux and AppArmour need to be disabled. I will dive into this and get it fixed. For now, let’s continue:
#AppArmour (Ubuntu)
ln -s /etc/apparmor.d/usr.sbin.libvirtd /etc/apparmor.d/disable/
ln -s /etc/apparmor.d/usr.lib.libvirt.virt-aa-helper /etc/apparmor.d/disable/
apparmor_parser -R /etc/apparmor.d/usr.sbin.libvirtd
apparmor_parser -R /etc/apparmor.d/usr.lib.libvirt.virt-aa-helper
SELinux (CentOS)
setenforce permissive
vim /etc/selinux/config
SELINUX=permissive
You can now add the host to CloudStack, either via de UI or the API.
Keep an eye on the agent log file:
less /var/log/cloudstack/agent/agent.logAfter a few minutes, the hypervisor is added and you should be able to spin up virtual machines! 🙂
When we spin up a VM, CloudStack does the orchestration. So, CloudStack is the one to talk to NSX to provide the network (lswitch) and NSX communicates with Open vSwitch on the hypervisor. The VM is provisioned by CloudStack and KVM/Libvirt makes sure the right virtual interfaces are plugged in Open vSwitch. This way VMs on different hypervisors can communicate over their own private guest network. All dynamically created without manual configuration. No more VLANs!
If it does not work right away, look at the different log files and see what happens. There usually are hints that help you solve the problem.
Conclusion
KVM hypervisors can be connected to NSX and using Open vSwitch you can build a Software Defined Networking setup. CloudStack is the orchestrator that connects the dots for us. I’ve played with this setup for some time now and I find it very fast. We’ll keep testing and probably create some patches for CloudStack. Great to see that the first KVM related pull request I sent is already merged 🙂
Looking forward to more KVM!
Recently I played with Open vSwitch and it’s awesome! Open vSwitch is a multilayer virtual switch and it brings a lot of flexibility in the way you can create interfaces and bridges in Linux. It’s also a Linux distribution independent way to configure these things. Switching in software!
To create a bridge, simply run:
ovs-vsctl add-br remibr0You can also create another bridge on top of it, to handle a VLAN for example:
ovs-vsctl add-br mgmt0 remibr0 101Even better, create a bond based on LACP:
ovs-vsctl add-bond remibr0 bond0 em49 em50 bond_mode=balance-tcp lacp=active other_config:lacp-time=fastThis is all quite nice but still basic. It gets interesting when you realise you can connect two switches like you can put a patch cable between physical switches. To test how cross platform this works, I setup two boxes: a CentOS 7 box and a Ubuntu 15.04 one. This shows it in a picture:
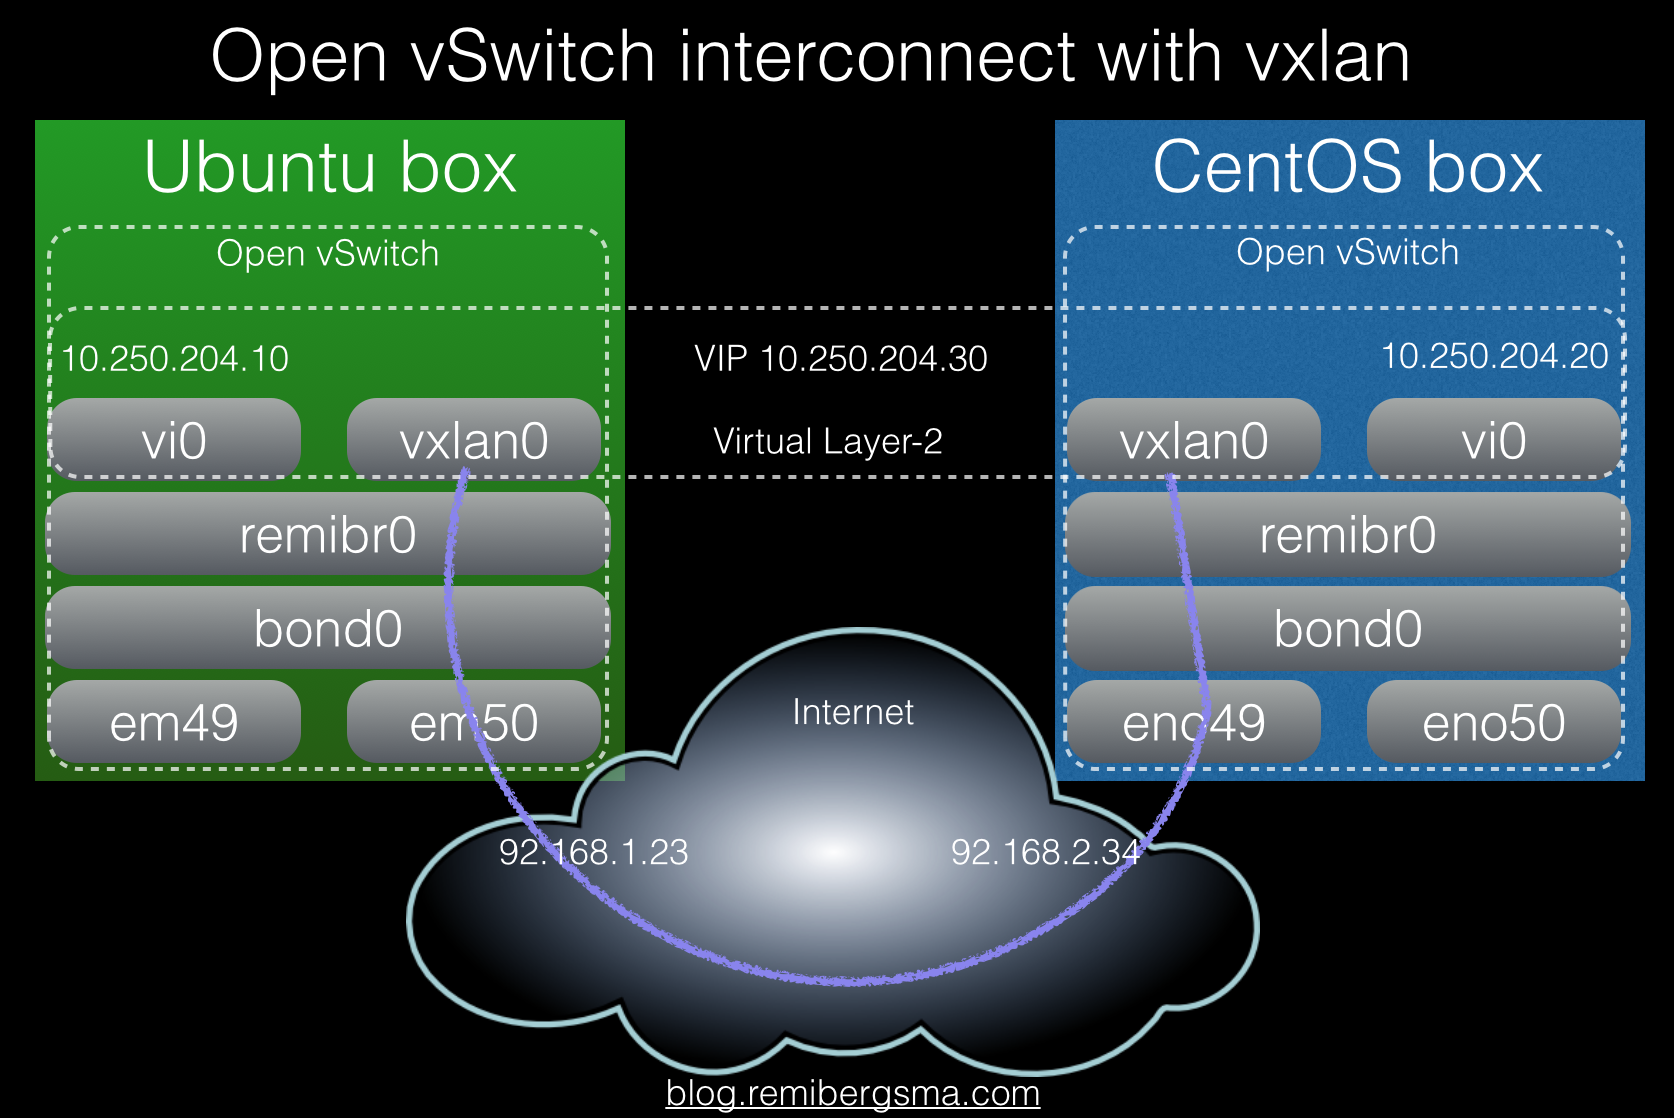
We’ll create a new bridge and add a vxlan interface that connects to the other vswitch. Then create a port on it and assign it an ip address. Installing Open vSwitch should be simple, as it is included in the releases.
Create the configuration and be sure to fill in the right ip addresses.
ovs-vsctl add-br remibr0
ovs-vsctl add-port remibr0 vxlan0 -- set Interface vxlan0 type=vxlan options:remote_ip=92.168.1.23
ovs-vsctl add-port remibr0 vi0 -- set Interface vi0 type=internal
ifconfig vi0 10.250.204.10/24 up
On the second box, bring up 10.25.204.20/24 on vi0.
Your config should look like this:
ovs-vsctl showf11505d7-199c-4fa9-9f3a-21016ab4fded
Bridge "remibr0"
Port "vxlan0"
Interface "vxlan0"
type: vxlan
options: {remote_ip="92.168.1.23"}
Port "remibr0"
Interface "remibr0"
type: internal
Port "vi0"
Interface "vi0"
type: internal
ovs_version: "2.3.1"And on the second box:
ovs-vsctl showOutput:
129f100b-1377-46bd-89ba-eaf1f1bc5162
 Bridge "remibr0"
   Port "vi0"
     Interface "vi0"
       type: internal
   Port "vxlan0"
     Interface "vxlan0"
       type: vxlan
       options: {remote_ip="92.168.2.34"}
   Port "remibr0"
     Interface "remibr0"
       type: internal
 ovs_version: "2.3.90"
As you can see, I used different versions on purpose. You can use two boxes that are the same, of course.
By now, a simple ping test should work:
PING 10.250.204.20 (10.250.204.20) 56(84) bytes of data.
64 bytes from 10.250.204.20: icmp_seq=1 ttl=64 time=0.019 ms
64 bytes from 10.250.204.20: icmp_seq=2 ttl=64 time=0.009 ms
^C
--- 10.250.204.20 ping statistics ---
2 packets transmitted, 2 received, 0% packet loss, time 999ms
rtt min/avg/max/mdev = 0.009/0.014/0.019/0.005 ms
And reversed:
PING 10.250.204.10 (10.250.204.10) 56(84) bytes of data.
64 bytes from 10.250.204.10: icmp_seq=1 ttl=64 time=1.47 ms
64 bytes from 10.250.204.10: icmp_seq=2 ttl=64 time=0.202 ms
^C
--- 10.250.204.10 ping statistics ---
2 packets transmitted, 2 received, 0% packet loss, time 1001ms
rtt min/avg/max/mdev = 0.202/0.839/1.477/0.638 ms
Create a virtual floating ip address
To make the demo a bit more advanced, let’s setup a virtual ip address on the interfaces that can travel between the switches. We use keepalived for this.
vim /etc/keepalived/keepalived.confAdd this:
global_defs {
 notification_email {
 [email protected]
 [email protected]
 [email protected]
 }
 notification_email_from [email protected]
 smtp_server 192.168.200.1
 smtp_connect_timeout 30
 router_id LVS_DEVEL
}
vrrp_instance VI_1 {
 state MASTER
 interface vi0
 virtual_router_id 51
 priority 200
 advert_int 1
 authentication {
 auth_type PASS
 auth_pass 1111
 }
 virtual_ipaddress {
 10.250.204.30/24
 }
}
Copy the config to the other box, be sure to have on MASTER and one BACKUP. Also, the priority of the MASTER should be 200 and the BACKUP 100. It’s just a demo, all it does it bring up an ip address.
Start them both and they should discover each other over the vi0 interfaces on the connected vswitches.
Try pinging the virtual ip address:
PING 10.250.204.30 (10.250.204.30) 56(84) bytes of data.
64 bytes from 10.250.204.30: icmp_seq=1 ttl=64 time=0.045 ms
64 bytes from 10.250.204.30: icmp_seq=2 ttl=64 time=0.031 ms
64 bytes from 10.250.204.30: icmp_seq=3 ttl=64 time=0.023 ms
^C
--- 10.250.204.30 ping statistics ---
3 packets transmitted, 3 received, 0% packet loss, time 1998ms
Depending on where the virtual address resides, the latency may be different:
PING 10.250.204.30 (10.250.204.30) 56(84) bytes of data.
64 bytes from 10.250.204.30: icmp_seq=1 ttl=64 time=0.481 ms
64 bytes from 10.250.204.30: icmp_seq=2 ttl=64 time=0.202 ms
64 bytes from 10.250.204.30: icmp_seq=3 ttl=64 time=0.215 ms
64 bytes from 10.250.204.30: icmp_seq=4 ttl=64 time=0.203 ms
^C
--- 10.250.204.30 ping statistics ---
4 packets transmitted, 4 received, 0% packet loss, time 2998ms
rtt min/avg/max/mdev = 0.202/0.275/0.481/0.119 ms
Now start a ping and stop keepalived, then start it again and stop it on the other side. You’ll miss a ping or two when it fails over and then it will recover just fine.
PING 10.250.204.30 (10.250.204.30) 56(84) bytes of data.
64 bytes from 10.250.204.30: icmp_seq=1 ttl=64 time=0.824 ms
64 bytes from 10.250.204.30: icmp_seq=2 ttl=64 time=0.167 ms
64 bytes from 10.250.204.30: icmp_seq=3 ttl=64 time=0.160 ms
64 bytes from 10.250.204.30: icmp_seq=4 ttl=64 time=0.148 ms
64 bytes from 10.250.204.30: icmp_seq=5 ttl=64 time=0.149 ms
From 10.250.204.10: icmp_seq=6 Redirect Host(New nexthop: 10.250.204.30)
From 10.250.204.10 icmp_seq=6 Redirect HostFrom 10.250.204.10: icmp_seq=7 Redirect Host(New nexthop: 10.250.204.30)
From 10.250.204.10 icmp_seq=7 Redirect Host64 bytes from 10.250.204.30: icmp_seq=8 ttl=64 time=0.012 ms
64 bytes from 10.250.204.30: icmp_seq=9 ttl=64 time=0.025 ms
64 bytes from 10.250.204.30: icmp_seq=10 ttl=64 time=0.012 ms
64 bytes from 10.250.204.30: icmp_seq=11 ttl=64 time=0.016 ms
64 bytes from 10.250.204.30: icmp_seq=12 ttl=64 time=0.011 ms
64 bytes from 10.250.204.30: icmp_seq=13 ttl=64 time=0.011 ms
From 10.250.204.10: icmp_seq=14 Redirect Host(New nexthop: 10.250.204.30)
From 10.250.204.10 icmp_seq=14 Redirect HostFrom 10.250.204.10: icmp_seq=15 Redirect Host(New nexthop: 10.250.204.30)
From 10.250.204.10 icmp_seq=15 Redirect Host64 bytes from 10.250.204.30: icmp_seq=16 ttl=64 time=0.323 ms
64 bytes from 10.250.204.30: icmp_seq=17 ttl=64 time=0.162 ms
64 bytes from 10.250.204.30: icmp_seq=18 ttl=64 time=0.145 ms
64 bytes from 10.250.204.30: icmp_seq=19 ttl=64 time=0.179 ms
64 bytes from 10.250.204.30: icmp_seq=20 ttl=64 time=0.147 ms
^C
--- 10.250.204.30 ping statistics ---
20 packets transmitted, 16 received, +4 errors, 20% packet loss, time 19000ms
rtt min/avg/max/mdev = 0.011/0.155/0.824/0.193 ms
Note on the MTU when travelling over the internet
vxlan is encapsulation and this obviously needs space in the packets send over the wire. If you travel over networks that have a default MTU of 1500, it may be wise to lower the MTU of the vi0 interfaces as this will prevent fragmentation. Lowering the MTU is a simple work-around. You could also have a look at GRE tunnels instead.
To alter the MTU:
ip link set dev vi0 mtu 1412You can make this persistent in Ubuntu’s ‘interfaces’ file and add ‘mtu 1400’. Red Hat alike systems have ‘ifcfg-*’ files for each interface. Add ‘MTU=1400’ to them to alter the MTU.
Conclusion
Although this is a simple demo, the real power comes when you use this to connect two different (virtual or physical) networks in different data centers. You’ll be able to create a Layer-2 network over Layer-3. It’s simple, fast and awesome.
 Our XenServer hypervisors use Nicira/NSX for Software Defined Networking (orchestrated by CloudStack).
We had to migrate from one controller to another and that could easily be done by changing the Open vSwitch configuration on the hypervisors, like this:
ovs-vsctl set-manager ssl:10.18.59.84:6632It will then get a list of all nodes and use those to communicate.
Although this works, I found that when rebooting the hypervisor it would revert to the old setting. Also, when a pool master fail-over happened, Xapi ran a xe toolstack-restart and that caused the whole cluster to revert to the old setting. Oops.
Changing it in Xapi was the solution:
xe pool-set-vswitch-controller address=10.18.59.84Now the change is persistent 🙂
Due to the Ghost bug aka CVE-2015-0235, we had to upgrade 500+ system vm’s. We’re running CloudStack 4.4.2. The version of the systemvm template it uses was 4.4.1 and so we created 4.4.2 and used that instead. It was quite some work to get it done so we thought it was worth sharing how we did it in this blog. I did this work together with my Schuberg Philis colleague Daan Hoogland.
1. Build new CloudStack RPM’s with MinVRVersion set to 4.4.2
Basically this was a single digit change in a single file (api/src/com/cloud/network/VirtualNetworkApplianceService.java).
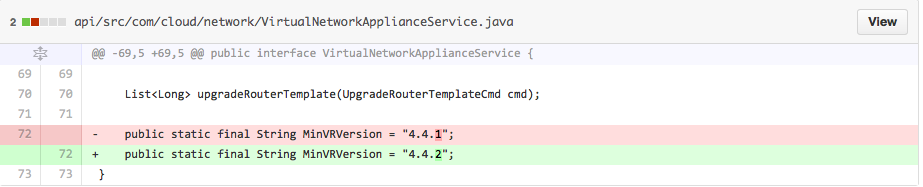
2. Build new systemvm with latest patches
Obviously we had to build a new systemvm template with this same version. We used the latest Debian 7 release:
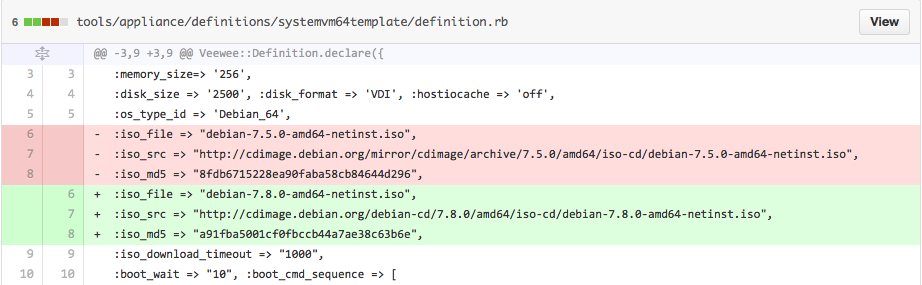
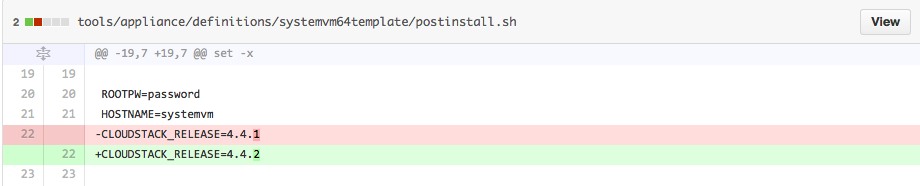
And set the version also to 4.4.2:
3. Upload the template to CloudStack
Upload the template as admin user. We couldn’t use systemvm-xenserver-4.4 as a name, because it was already there. So we gave it a temporary name: systemvm-xenserver-4.4.2.
Wait until they are READY.
4. Stop CloudStack management servers
Unfortunately you need to stop CloudStack. First of all because we’re going to upgrade the RPM’s. Second to get the new template registered.
Also, since we will hack the SQL database in the next step (or should I say: we used the SQL-API) it’s better to do this when CloudStack is not running.
5. Hack the SQL database
When the templates are downloaded, we made the following changes:
– renamed systemvm-xenserver-4.4 to systemvm-xenserver-4.4-old
– renamed systemvm-xenserver-4.4.2 to systemvm-xenserver-4.4
– set the type of systemvm-xenserver-4.4.2 to SYSTEM
Get an overview with this query:
SELECT * FROM cloud.vm_template where type='SYSTEM';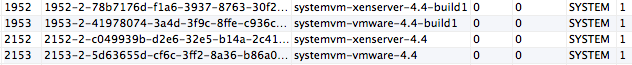
Example of update query:
UPDATE `cloud`.`vm_template` SET `name`='systemvm-xenserver-4.4', `type`='SYSTEM' WHERE `id`='2152';
UPDATE `cloud`.`vm_template` SET `name`='systemvm-vmware-4.4', `type`='SYSTEM' WHERE `id`='2153';
As you can see, in our case the old and new template id’s were as follows:
1952: old template, 2152 new
1953: old template, 2153 new
Finally, you need to update the vm_template_id from old -> new like in this example:
UPDATE `cloud`.`vm_instance` SET `vm_template_id`='2152' WHERE `vm_template_id`='1952' and removed is NULL;
UPDATE `cloud`.`vm_instance` SET `vm_template_id`='2153' WHERE `vm_template_id`='1953' and removed is NULL;
6. Install new CloudStack RPM’s
Now that CloudStack is still down, upgrade the RPM’s. This is a quick install as there are almost no changes.
7. Start the management servers
It’s time to start the management servers again. When it’s ready, check the virtual routers:

All flags RequiresUpgrade are set!
8. Destroy SSVM and CP
We had to destroy the Secondary Storage VM’s and Console Proxies for them to get recreated with the new templates. Rebooting did not work.
9. Reboot routers
Just reboot your routers and they get upgraded automatically!
We used internal developed tooling to do this automated. The tools send maintenance notifications to the tenant when their router is upgraded (and when it’s finished). We’ll open source the tools in the coming months, so stay tuned!
Conclusion
I think we need an easier way to do this 😉
Happy patching!

 | Lukas F. on Home-key in OSX-Terminal |
| Ryan Ziegler on Forwarding a local MySQL socket to a remote MySQL server |
 | Robin on HOWTO quickly add a route in Mac OSX |
| Robert K. on HOWTO remove null characters from a file |
| Dirk on Alt-key in OSX-Terminal |
| Mohammad on Alt-key in OSX-Terminal |
 | Mc.Sim on RRDtool: moving data between 32bit and 64bit architectures |
 | Bertl on HOWTO solve OpenLDAP bdb_equality_candidates errors |
 | Shashi on Setting locales correctly on Mac OSX Terminal application |
 | Sayling Low on Alt-key in OSX-Terminal |
 | Roger on Setting locales correctly on Mac OSX Terminal application |
 | belwardblog on HOWTO discover the ip address of a Raspberry Pi |
 | Guilherme Caeiro Dias on Setting locales correctly on Mac OSX Terminal application |
| Terminal Show Multiple Languages – Config9.com on Setting locales correctly on Mac OSX Terminal application |